linker
Linker I/O tricks and their downsides
mold and wild enable several tricks by default that other linkers don't do. This post looks at three of them:
- overwrite an existing output file in place instead of creating a new file
- fork a child to do the link, so that the parent can exit before the child releases its memory
- ask the kernel for transparent huge pages
Each saves a few percent of wall time in an edit-relink loop. Each also breaks an assumption that build systems, debuggers, and profilers make about a process. I measured what they save and what they break.
Setup: Linux 6.18, i7-14700K (28 threads), ext4 on a SATA SSD, transparent huge pages enabled=always.
GNU ld 2.47, gold 2.47, LLD 23, mold 2.42.1 (TODO: I used the Rust port under development; check against the C++ release), wild at commit 47cc8e8e.
lld 23 ELF changes
LLVM 23.1 has been released. As usual, I maintain lld/ELF and as volunteer work have added some notes to https://github.com/llvm/llvm-project/blob/release/23.x/lld/docs/ReleaseNotes.rst.
Like last time, I used Claude Code to summarize git log llvmorg-23-init..origin/release/23.x -- lld/ELF, excluding changes cherry-picked into 22.x (git rev-list llvmorg-23-init..llvmorg-22.1.8 -- lld), and then edited the draft.
This was a busy cycle: 141 commits landed in lld/ELF between the branch point (2026-01-13) and 23.1.0-rc1 (2026-07-16), compared with 72 in the 22 cycle. Much of the increase is performance work, which I described in Recent lld/ELF performance improvements. lld 23 is the first release that ships all of it.
…Recent lld/ELF performance improvements
Updated in 2026-05.
Since the LLVM 22 branch was cut, I've landed patches that parallelize more link phases and cut task-runtime overhead.
This post compares current main against lld 22.1, mold, and wild.
Headline: a Release+Asserts clang --gc-sections link is 1.34x as fast as lld 22.1; Chromium debug with --gdb-index is 1.09x as fast. mold and wild are still ahead — the last section explains why.
Call relocation types
Most architectures encode direct branch/call instructions with a PC-relative displacement. This post discusses a specific category of branch relocations: those used for direct function calls and tail calls. Some architectures use two ELF relocation types for a call instruction:
# i386, x86-64
call foo              # R_386_PC32, R_X86_64_PC32
call foo@plt          # R_386_PLT32, R_X86_64_PLT32

# m68k
bsr.l foo             # R_68K_PC32
bsr.l foo@plt         # R_68K_PLT32

# s390/s390x
brasl %r14, foo       # R_390_PC32DBL
brasl %r14, foo@plt   # R_390_PLT32DBL

# sparc
call    foo, 0        # not PIC: R_SPARC_WDISP30
call foo, 0 # gas -KPIC: R_SPARC_WPLT30lld 22 ELF changes
For those unfamiliar, lld is the LLVM linker, supporting PE/COFF, ELF, Mach-O, and WebAssembly ports. These object file formats differ significantly, and each port must follow the conventions of the platform's system linker. As a result, the ports share limited code (diagnostics, memory allocation, etc) and have largely separate reviewer groups.
With LLVM 22.1 releasing soon, I've added some notes to the https://github.com/llvm/llvm-project/blob/release/22.x/lld/docs/ReleaseNotes.rst as an lld/ELF maintainer. As usual, I've reviewed almost all the patches not authored by me.
For the first time, I used an LLM agent (Claude Code) to help look through commits (git log release/21.x..release/22.x -- lld/ELF) and draft the release notes.
Despite my request to only read lld/ELF changes, Claude Code also crafted notes for other ports, which I retained since their release notes had been quite sparse for several releases.
Changes back ported to the 21.x release are removed (git log --oneline llvmorg-22-init..llvmorg-21.1.8 -- lld).
I'll delve into some of the key changes.
…Long branches in compilers, assemblers, and linkers
Branch instructions on most architectures use PC-relative addressing with a limited range. When the target is too far away, the branch becomes "out of range" and requires special handling.
Consider a large binary where main() at address 0x10000 calls foo() at address 0x8010000-over 128MiB away.
On AArch64, the bl instruction can only reach ±128MiB, so this call cannot be encoded directly.
Without proper handling, the linker would fail with an error like "relocation out of range."
The toolchain must handle this transparently to produce correct executables.
This article explores how compilers, assemblers, and linkers work together to solve the long branch problem.
- Compiler (IR to assembly): Handles branches within a function that exceed the range of conditional branch instructions
- Assembler (assembly to relocatable file): Handles branches within a section where the distance is known at assembly time
- Linker: Handles cross-section and cross-object branches discovered during final layout
Remarks on SFrame
SFrame is a new stack walking format for userspace profiling, inspired by Linux's in-kernel ORC unwind format.
While SFrame eliminates some .eh_frame CIE/FDE overhead, it sacrifices functionality (e.g., personality, LSDA, callee-saved registers) and flexibility, and its stack offsets are less compact than .eh_frame's bytecode-style CFI instructions.
In llvm-project executables I've tested on x86-64, .sframe section is 20% larger than .eh_frame.
It also remains significantly larger than highly compact schemes like Windows ARM64 unwind codes.
SFrame describes three elements for each function:
- Canonical Frame Address (CFA): The base address for stack frame calculations
- Return address
- Frame pointer
An .sframe section follows a straightforward layout:
- Header: Contains metadata and offset information
- Auxiliary header (optional): Reserved for future extensions
- Function Descriptor Entries (FDEs): Array describing each function
- Frame Row Entries (FREs): Arrays of unwinding information per function
lld 21 ELF changes
LLVM 21.1 have been released. As usual, I maintain lld/ELF and have added some notes to https://github.com/llvm/llvm-project/blob/release/21.x/lld/docs/ReleaseNotes.rst. I've meticulously reviewed nearly all the patches that are not authored by me. I'll delve into some of the key changes.
…Understanding alignment - from source to object file
Updated in 2026-04.
Alignment refers to the practice of placing data or code at memory addresses that are multiples of a specific value, typically a power of 2. This is typically done to meet the requirements of the programming language, ABI, or the underlying hardware. Misaligned memory accesses might be expensive or will cause traps on certain architectures.
This blog post explores how alignment is represented and managed as C++ code is transformed through the compilation pipeline: from source code to LLVM IR, assembly, and finally the object file. We'll focus on alignment for both variables and functions.
…lld 20 ELF changes
LLVM 20 will be released. As usual, I maintain lld/ELF and have added some notes to https://github.com/llvm/llvm-project/blob/release/20.x/lld/docs/ReleaseNotes.rst. I've meticulously reviewed nearly all the patches that are not authored by me. I'll delve into some of the key changes.
…Removing global state from LLD
LLD, the LLVM linker, is a mature and fast linker supporting multiple binary formats (ELF, Mach-O, PE/COFF, WebAssembly). Designed as a standalone program, the code base relies heavily on global state, making it less than ideal for library integration. As outlined in RFC: Revisiting LLD-as-a-library design, two main hurdles exist:
- Fatal errors: they exit the process without returning control to the caller. This was actually addressed for most scenarios in 2020 by utilizing
llvm::sys::Process::Exit(val, /*NoCleanup=*/true)andCrashRecoveryContext(longjmpunder the hood). - Global variable conflicts: shared global variables do not allow two concurrent invocation.
I understand that calling a linker API could be convenient, especially when you want to avoid shipping another executable (which can be large when you link against LLVM statically). However, I believe that invoking LLD as a separate process remains the recommended approach. There are several advantages:
- Build system control: Build systems gain greater control over scheduling and resource allocation for LLD. In an edit-compile-link cycle, the link could need more resources and threading is more useful.
- Better parallelism management
- Global state isolation: LLVM's global state (primarily
cl::optandManagedStatic) is isolated.
lld 19 ELF changes
LLVM 19 will be released. As usual, I maintain lld/ELF and have added some notes to https://github.com/llvm/llvm-project/blob/release/19.x/lld/docs/ReleaseNotes.rst. I've meticulously reviewed nearly all the patches that are not authored by me. I'll delve into some of the key changes.
…Mapping symbols: rethinking for efficiency
In object files, certain code patterns embed data within instructions or transitions occur between instruction sets. This can create hurdles for disassemblers, which might misinterpret data as code, resulting in inaccurate output. Furthermore, code written for one instruction set could be incorrectly disassembled as another. To address these issues, some architectures (Arm, C-SKY, NDS32, RISC-V, etc) define mapping symbols to explicitly denote state transition. Let's explore this concept using an AArch32 code example:
…Linker compatibility and the "User-Agent" problem
The output of ld.lld -v includes a message "compatible with GNU linkers" to address detection mechanism used by GNU Libtool.
This problem is described by Software compatibility and our own "User-Agent" problem.
The latest m4/libtool.m4 continues to rely on a GNU check.
Light ELF: exploring potential size reduction
ELF's design emphasizes natural size and alignment guidelines for its control structures.
While ensured efficient processing in the old days, this can lead to larger file sizes.
I propose "Light ELF" (EV_LIGHT, version 2) – a whimsical exploration inspired by Light Elves of Tolkien's legendarium (who had seen the light of the Two Trees in Valinor).
A compact relocation format for ELF
This article introduces CREL (previously known as RELLEB), a new relocation format offering incredible size reduction (LLVM implementation in my fork).
ELF's design emphasizes natural size and alignment guidelines for its control structures. This principle, outlined in Proceedings of the Summer 1990 USENIX Conference, ELF: An Object File to Mitigate Mischievous Misoneism, promotes ease of random access for structures like program headers, section headers, and symbols.
…All data structures that the object file format defines follow the "natural" size and alignment guidelines for the relevant class. If necessary, data structures contain explicit padding to ensure 4-byte alignment for 4-byte objects, to force structure sizes to a multiple of four, etc. Data also have suitable alignment from the beginning of the file. Thus, for example, a structure containing an Elf32_Addr member will be aligned on a 4-byte boundary within the file. Other classes would have appropriately scaled definitions. To illustrate, the 64-bit class would define Elf64 Addr as an 8-byte object, aligned on an 8-byte boundary. Following the strictest alignment for each object allows the format to work on any machine in a class. That is, all ELF structures on all 32-bit machines have congruent templates. For portability, ELF uses neither bit-fields nor floating-point values, because their representations vary, even among pro- cessors with the same byte order. Of course the programs in an ELF file may use these types, but the format itself does not.
MMU-less systems and FDPIC
This article describes ABI and toolchain considerations about systems without a Memory Management Unit (MMU). We will focus on FDPIC and the in-development FDPIC ABI for RISC-V, with updates as I delve deeper into the topic.
Embedded systems often lack MMUs, relying on real-time operating systems (RTOS) like VxWorks or special Linux configurations (CONFIG_MMU=n).
In these systems, the offset between the text and data segments is often not knwon at compile time.
Therefore, a dedicated register is typically set to somewhere in the data segment and writable data is accessed relative to this register.
Why is the offset not known at compile time? There are primarily two reasons.
First, eXecute in Place (XIP), where code resides in ROM while the data segment is copied to RAM. Therefore, the offset between the text and data segments is often not known at compile time.
Second, all processes share the same address space without MMU. However, it is still desired for these processes to share text segments. Therefore needs a mechanism for code to find its corresponding data.
…lld 18 ELF changes
LLVM 18 will be released. As usual, I maintain lld/ELF and have added some notes to https://github.com/llvm/llvm-project/blob/release/18.x/lld/docs/ReleaseNotes.rst. I've meticulously reviewed nearly all the patches that are not authored by me. I'll delve into some of the key changes.
…Toolchain notes on z/Architecture
This article describes some notes about z/Architecture with a focus on the ELF ABI and ELF linkers. An lld/ELF patch sparked my motivation to study the architecture and write this post.
z/Architecture is a big-endian mainframe computer architecture supporting 24-bit, 31-bit, and 64-bit addressing modes.
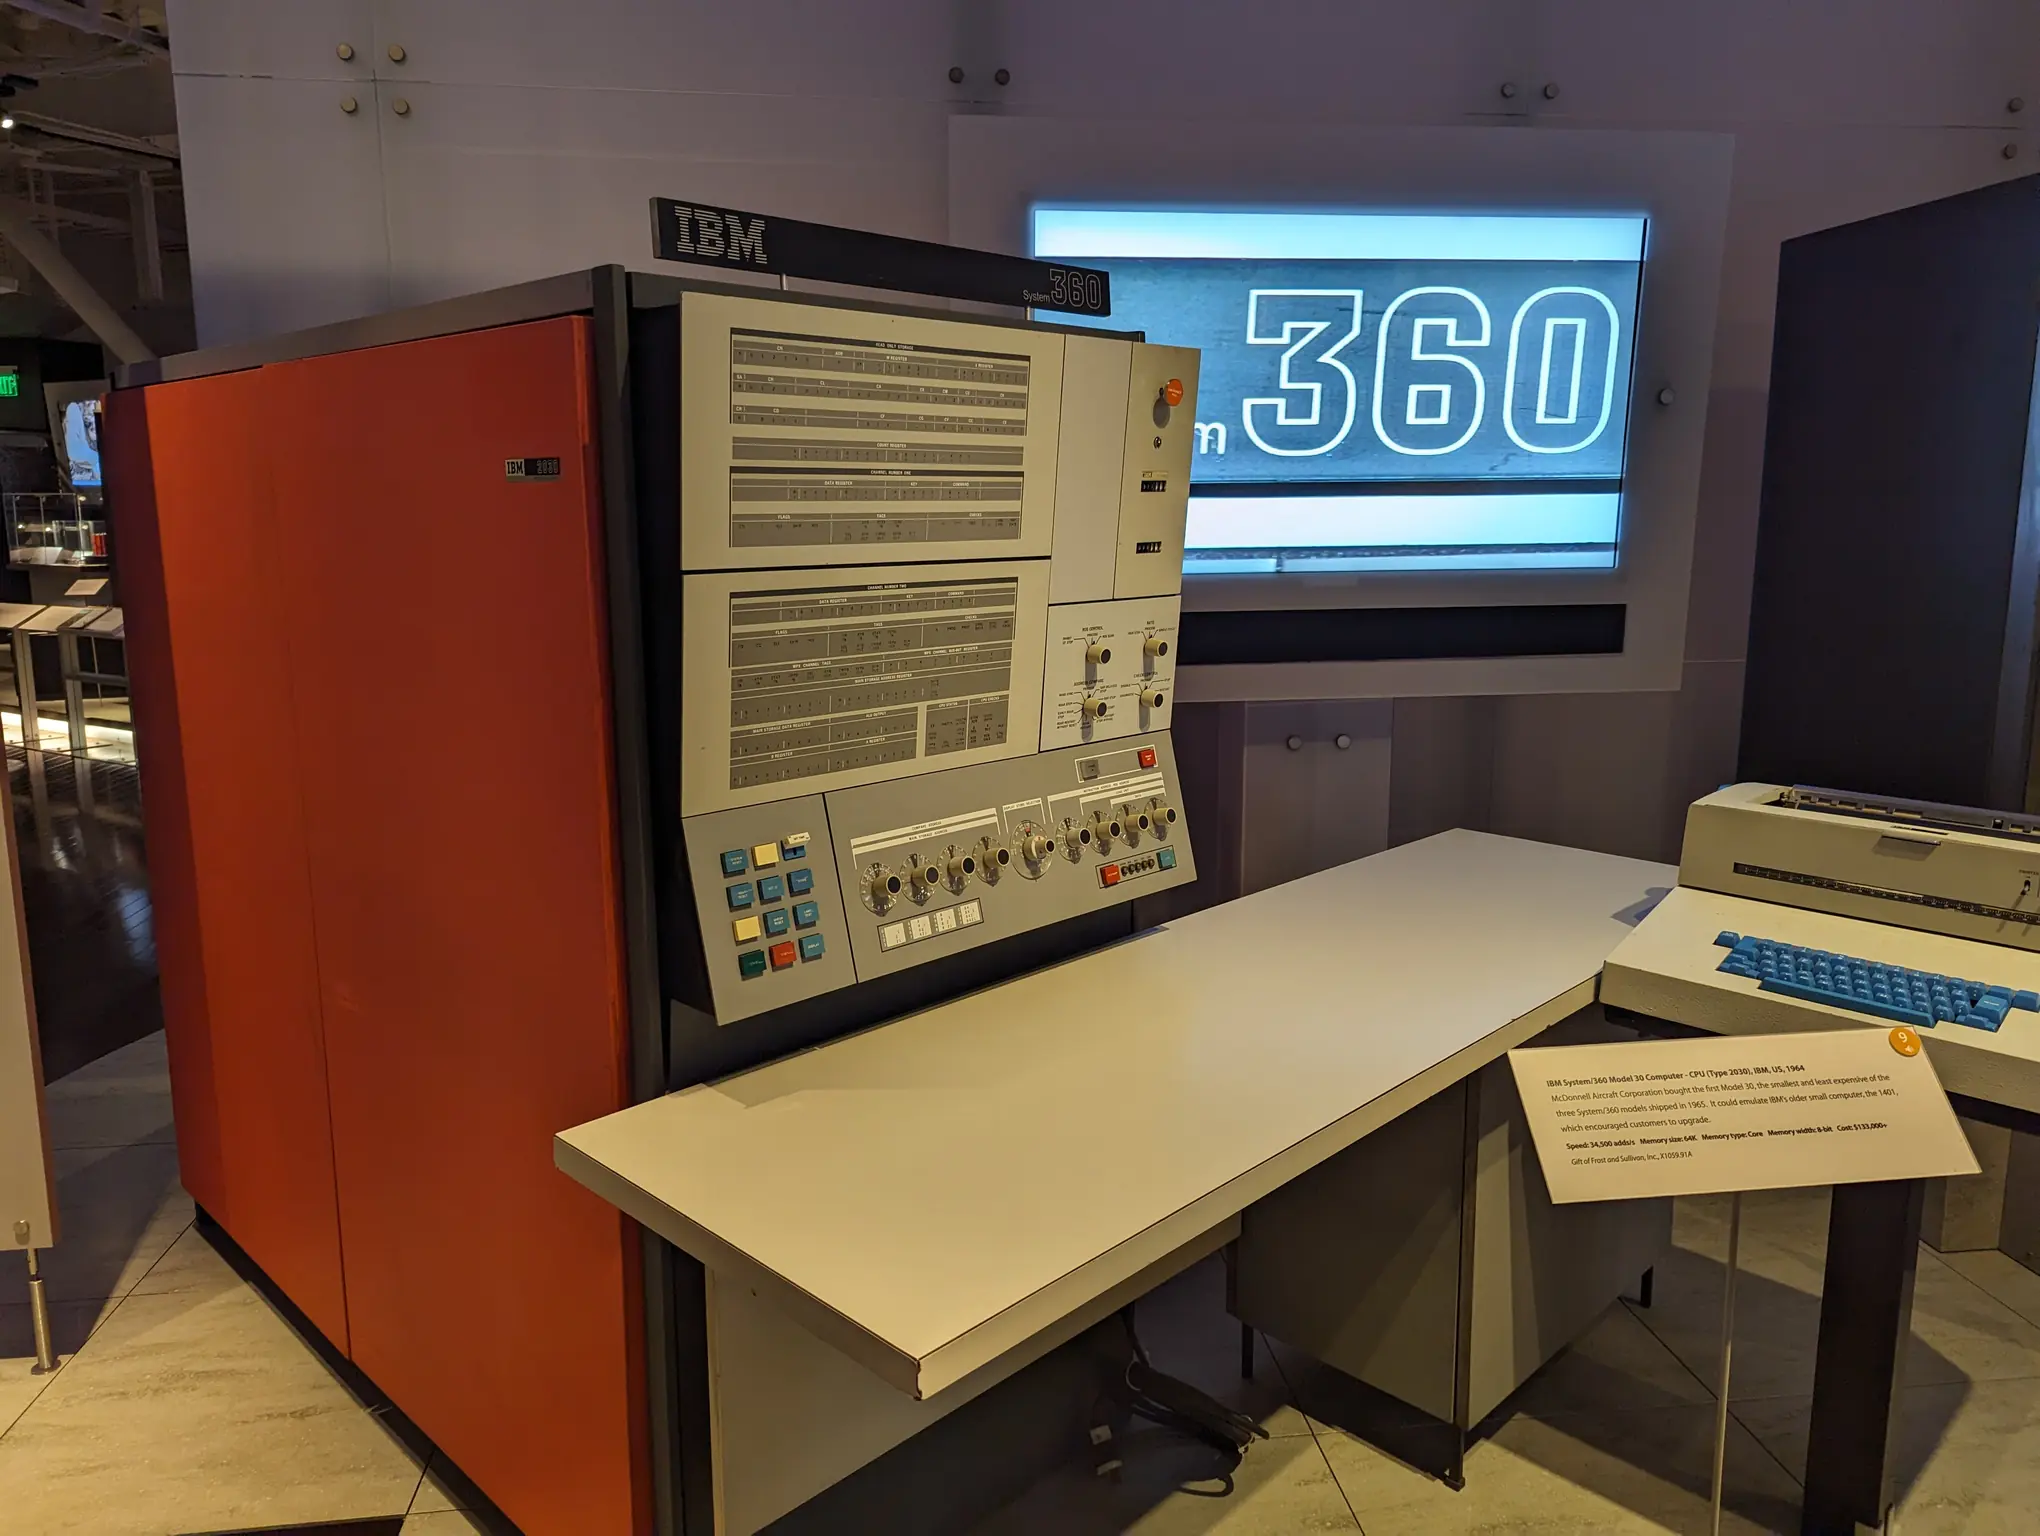
It is the latest generation in a lineage stretching back to the 1964 with IBM System/360 (32-bit general-purpose registers and 24-bit addressing).
This lineage includes System/370 (1970), System/370 Extended Architecture (1983), Enterprise Systems Architecture/370 (1988), and Enterprise Systems Architecture/390 (1990).
For a deeper dive into the design choices behind z/Architecture's extension from ESA/390, you can refer to "Development and attributes of z/Architecture."
Exploring object file formats
My journey with the LLVM project began with a deep dive into the world of lld and binary utilities. Countless hours were spent unraveling the intricacies of object file formats and shaping LLVM's relevant components. Though my interests have since broadened, object file formats remain a personal fascination, often drawing me into discussions around potential changes within LLVM.
This article compares several prominent object file formats, drawing upon my experience and insights.
At the heart of each format lies the representation of essential components like symbols, sections, and relocations. For each control structure, We'll begin with ELF, a widely used format, before venturing into the landscapes of other notable formats.
…Exploring the section layout in linker output
Updated in 2026-03.
This article describes section layout and its interaction with dynamic loaders and huge pages.
Let's begin with a Linux x86-64 example involving global variables exhibiting various properties such as read-only versus writable, zero-initialized versus non-zero, and more.
#include <stdio.h>
const int ro = 1;
int w0, w1 = 1;
int *const pw0 = &w0;
int main() {
  printf("%d %d %d %p\n", ro, w0, w1, pw0);
}Linker notes on PE/COFF
Updated in 2025-05.
This article describes linker notes about Portable Executable (PE) and Common Object File Format (COFF) used on Windows and UEFI environments.
In ELF, an object file can be a relocatable file, an executable file, or a shared object file. On Windows, the term "object file" usually refers to relocatable files like ELF. Such files use the Common Object File Format (COFF) while image files (e.g. executables and DLLs) use the Portable Executable (PE) format.
A look at linkers
MSVC Linker is the reference linker on Windows.
GNU ld supports Windows thanks to the MinGW effort. Here are some common BFD emulations for PE targets:
i386pe: For 32-bit Intel x86 architectures.i386pep: For 64-bit Intel x86-64 architectures.arm64pe: For 64-bit ARM (AArch64) architectures.
For instance, you can use a command like ld.bfd -m i386pep a.o b.o to link two object files into a PE executable.
Many options on Linux can also be used when targeting PE/COFF.
The LLVM linker offers two modes of operation that are relevant to PE/COFF:
lld-link: In this mode, lld emulates the MSVC linker, making it a fast viable alternative.ld.lld: When invoked with a PE emulation (like-m i386pep), lld emulates GNU ld. Code inlld/MinGWtranslates GNU ld options to link.exe options.
GNU ld implements relocatable linking that is not available in other linkers.
Input files
The input files to the linker can be object files, archive files, and import libraries. GNU ld and lld-link allow linking against DLL files without an import library.
…DSO undef and non-exported definition
DSO undef and non-exported def
If a DSO has an undefined STB_GLOBAL symbol that is defined in a relocatable object file but not exported, should the --no-allow-shlib-undefined feature report an error?
You may want to check out Dependency related linker options for a discussion of this option and the symbol exporting rule.
Toolchain notes on MIPS
This article describes some notes about MIPS with a focus on the ELF object file format, GCC, binutils, and LLVM/Clang.
In the llvm-project project, I sometimes find myself assigned as a reviewer for MIPS patches. I want to be transparent that I have no interest in MIPS, but my concern lies with the specific components that are impacted (Clang driver, ld.lld, MC, compiler-rt, etc.). Therefore, regrettably, I have to spend some time studying MIPS.
…Using copper as a mirror, one can straighten their attire; using the past as a mirror, one can understand rise and fall; using people as a mirror, one can discern gains and losses. -- 贞观政要
My involvement with LLVM 17
LLVM 17 will soon be relased. This post provides a summary of my contributions in this release cycle to record my learning progress.
…lld 17 ELF changes
LLVM 17 will be released. As usual, I maintain lld/ELF and have added some notes to https://github.com/llvm/llvm-project/blob/release/17.x/lld/docs/ReleaseNotes.rst. Here I will elaborate on some changes.
…Compressed arbitrary sections
This article describes SHF_ALLOC|SHF_COMPRESSED sections in ELF and lld's linker option --compress-sections to compress arbitrary sections.
Relocation overflow and code models
Updated in 2025-12.
When linking an oversized executable, it is possible to encounter errors such as relocation truncated to fit: R_X86_64_PC32 against `.text' (GNU ld) or relocation R_X86_64_PC32 out of range (ld.lld).
These diagnostics are a result of the relocation overflow check, a feature in the linker.
% gcc -fuse-ld=bfd @response.txt
...
a.o: in function `_start':
(.text+0x0): relocation truncated to fit: R_X86_64_PC32 against `.text'
% gcc -fuse-ld=lld @response.txt
ld.lld: error: a.o:(.text+0x0): relocation R_X86_64_PC32 out of range: -2147483649 is not in [-2147483648, 2147483647]; references section '.text'
This article aims to explain why such issues can occur and provides insights on how to mitigate them.
…Linker notes on AArch32
UNDER CONSTRUCTION
This article describes target-specific details about AArch32 in ELF linkers. I described AArch64 in a previous article.
AArch32 is the 32-bit execution state for the Arm architecture and runs the A32 and T32 instruction sets. A32 refers to the old ISA with a 32-bit fixed width, while T32 refers to the mixed 16-bit and 32-bit Thumb2 instructions.
"AArch32", "A32", and "T32" are new names. Many projects use "ARM", "Arm", or "arm" as their port name.
…ELF hash function may overflow
This article describes an interesting overflow bug in the ELF hash function.
The System V Application Binary Interface (generic ABI) specifies the ELF object file format.
When producing an executable or shared object file needing a dynamic symbol table (.dynsym), a linker generates a .hash section with type SHT_HASH to hold a symbol hash table.
A DT_HASH tag is produced to hold the address of .hash.
The hash table is used by a dynamic loader to perform symbol lookup (for dynamic relocations and dlsym family functions).
A detailed description of the format can be found in ELF: symbol lookup via DT_HASH.
lld 16 ELF changes
llvm-project 16 was just released. I added some lld/ELF notes to https://github.com/llvm/llvm-project/blob/release/16.x/lld/docs/ReleaseNotes.rst. Here I will elaborate on some changes.
…Linker notes on AArch64
This article describes target-specific details about AArch64 in ELF linkers. AArch64 is the 64-bit execution state for the Arm architecture. The AArch64 execution state runs the A64 instruction set. The AArch32 and AArch64 execution states use very different instruction sets, so many pieces of software use two ports for the two execution states of the Arm architecture.
There were the "ARM architecture" and the "ARM instruction set", leading to many software projects using "ARM" or "arm" as their port names. In 2011, ARMv8 introduced two execution states, AArch32 and AArch64. The previous instruction sets "ARM" and "Thumb" were renamed to "A32" and "T32", respectively. In 2017, the architecture was renamed to the "Arm architecture" to reflect the rebranding of the company name. So, the "ARMv8-A" architecture profile is now named "Armv8-A".
For the AArch64 execution state, while many projects use "AArch64" as their port name, for legacy reasons, macOS, Windows, the Linux kernel, and some BSD operating systems unfortunately use "arm64". (Support for AArch64 was added to the Linux kernel in version 3.7. Initially, the patch set was named "aarch64", but it was later changed at the request of kernel developers.)
…Linker notes on Power ISA
This article describes target-specific details about Power ISA in ELF linkers. Initially there was IBM POWER. The 1991 Apple–IBM–Motorola alliance created PowerPC. In 2006, the architecture was rebranded as Power ISA. According to the ISA manual, "In 2006, Freescale and IBM collaborated on the creation of the Power ISA Version 2.03, which represented the reunification of the architecture by combining Book E content with the more general purpose PowerPC Version 2.02."
The terms "PowerPC" and "powerpc" remain popular in numerous places, including the powerpc-*-*-* and powerpc64-*-*-* in official target triple names.
The abbreviation "PPC" ("ppc") is used in numerous places as well.
For simplicity, I will refer to the 32-bit architecture as "PPC32" and the 64-bit architecture as "PPC64".
We will see how the lack of PC-relative addressing before Power10 has caused great complexity to the ABI and linkers.
…Linker notes on x86
Updated in 2024-01.
This article describes target-specific details about x86 in ELF linkers. I will use "x86" to refer to both x86-32 and x86-64.
…Relocatable linking
Updated in 2025-02.
In GNU ld, -r produces a relocatable object file. This is known as relocatable linking or partial linking.
This mode suppresses many passes done for an executable or shared object output (in -no-pie/-pie/-shared modes).
-r, -no-pie, -pie, and -shared specify 4 different modes. The 4 options are mutually exclusive.
The relocatable output can be used for analysis and binary manipulation. Then, the output can be used to link the final executable or shared object.
clang -pie a.o b.o

# ==>

clang -r a.o b.o -o r.o
clang -pie r.o
Let's go through various linker passes and see how relocatable linking changes the operation.
…ODR violation detection
This article describes how to detect C++ One Definition Rule (ODR) violations. There are many good resources on the Internet about how ODR violations can introduce subtle bugs, so I will not repeat that here.
…lld linked musl on PowerPC64
I was asked about a segfault related to lld linked musl libc.so on PowerPC64.
/usr/lib/ld-musl-powerpc64le.so.1 /path/to/thingworked. The kernel ELF loader loads rtld and rtld loads the executable./path/to/thingsegfaulted. The kernel ELF loader loads both rtld and the executable.
Therefore the bug is likely due to a difference between the two modes.
…lld 15 ELF changes
llvm-project 15 was just released. I added some lld/ELF notes to https://github.com/llvm/llvm-project/blob/release/15.x/lld/docs/ReleaseNotes.rst. Here I will elaborate on some changes.
…RISC-V linker relaxation in lld
On 2022-07-07, I added a RISC-V linker relaxation framework in ld.lld and implemented R_RISCV_ALIGN/R_RISCV_CALL/R_RISCV_CALL_PLT relaxation.
The changes will be included in the next llvm-project release 15.0.0.
This post describes the implementation.
See The dark side of RISC-V linker relaxation for more information about RISC-V linker relaxation.
…Analysis and introspection options in linkers
Updated in 2026-01.
Reproduce tarball
LLD offers a convenient feature to bundle all input files into a tarball, making it easier to experiment with different linker options. Use either of these commands:
clang -fuse-ld=lld -Wl,--reproduce=/tmp/rep.tar a.o b.o
LLD_REPRODUCE=/tmp/rep.tar clang -fuse-ld=lld a.o b.o
Then unpack the tarball, navigate to the directory, and invoke LLD with the response file:
cd /tmp; tar xf rep.tar; cd rep
ld.lld @response.txt # append options like -y foo
The response file includes the --chroot option, which GNU ld does not support.
In most cases, you can simply remove this option to examine GNU ld's behavior.
ld.bfd @response.txtSymbol related
--trace-symbol=<sym>
Alias: -y sym
lld 14 ELF changes
llvm-project 14 will be released soon. I added some lld/ELF notes to https://github.com/llvm/llvm-project/blob/release/14.x/lld/docs/ReleaseNotes.rst. Here I will elaborate on some changes.
…All about COMMON symbols
Programming language behavior
FORTRAN 77 COMMON blocks compiled to COMMON symbols. You could declare a COMMON block in more than one file, with each specifying the number, type, and size of the variable. The linker allocated enough space to satisfy the largest size.
…Compressed debug sections
Updated in 2024-05.
Binary sizes are important. Filesystem compression is ergonomic but typically does not leverage application information well. Compressing allocable sections (text, data) increases program startup time and introduces memory overhead. In addition, filesystem compression is not sufficiently portable.
Debug sections are large and contribute to a significant portion of the binary size. Therefore, it is appealing to compress debug sections.
Here is a -DCMAKE_BUILD_TYPE=Debug build directory of llvm-project where I just ran ninja clang (on 2022-10-21).
Here are the total sizes of .o files, text sections, and debug sections.
It is typical that the debug information is often much larger than text sections.
% stat -c %s **/*.o | awk '{s+=$1} END{print s}'
1464767464
% readelf -WS **/*.o | awk 'BEGIN{FPAT="\\[.*?\\]|\\S+"} $2~/\.text/{d += strtonum("0x"$6)} END{print d}'
210026370
% readelf -WS **/*.o | awk 'BEGIN{FPAT="\\[.*?\\]|\\S+"} $2~/\.debug_/{d += strtonum("0x"$6)} END{print d}'
631069751
% readelf -WS **/*.o | awk 'BEGIN{FPAT="\\[.*?\\]|\\S+"} $2~/\.rela\.debug_/{d += strtonum("0x"$6)} END{print d}'
78448968
Some assemblers and linkers offer a feature to compress debug sections.
llvm-objcopy supports --compress-debug-sections=zlib to compress debug sections. We can use the option to check what if we compress debug sections for the assembler.
% for i in **/*.o; do /tmp/Rel/bin/llvm-objcopy --compress-debug-sections=zlib $i /tmp/c/o && readelf -WS /tmp/c/o | awk 'BEGIN{FPAT="\\[.*?\\]|\\S+"} $2~/\.debug_/{d += strtonum("0x"$6)} END{print d}'; done | awk '{s+=$1} END{print s}'
161691798
For debug sections, we have a compression ratio of 3.90! The total .o size is 995438992 bytes, 68% of the original.
Then let's check zstd.
% for i in **/*.o; do /tmp/Rel/bin/llvm-objcopy --compress-debug-sections=zstd $i /tmp/c/o && readelf -WS /tmp/c/o | awk 'BEGIN{FPAT="\\[.*?\\]|\\S+"} $2~/\.debug_/{d += strtonum("0x"$6)} END{print d}'; done | awk '{s+=$1} END{print s}'
159341878
To check whether an object file has compressed debug sections, we can use readelf.
% readelf -S a.o
...
Section Headers:
  [Nr] Name              Type            Address          Off    Size   ES Flg Lk Inf Al
...
  [ 5] .debug_abbrev     PROGBITS        0000000000000000 000080 000087 00   C  0   0  8
In the readelf -S output, the Flg column describes sh_flags where C indicates the SHF_COMPRESSED flag.
% readelf -t a.o
...
Section Headers:
  [Nr] Name
       Type            Address          Off    Size   ES   Lk Inf Al
       Flags
...
  [ 5] .debug_abbrev
       PROGBITS        0000000000000000 000080 000087 00   0   0  8
       [0000000000000800]: COMPRESSED
       ZLIB, 0000000000000093, 1
History
In 2007-11, Craig Silverstein added --compress-debug-sections=zlib to gold.
When the option was specified, gold compressed the content of a .debug* section with zlib and changed the section name to .debug*.zlib.$uncompressed_size.
Archives and --start-lib
Updated in 2026-02.
.a archives
Unix-like systems represent static libraries as .a archives.
A .a archive consists of a header and a collection of files with file member header.
Its usage is tightly coupled with the linker.
An archive almost always contains only relocatable object files and the linker has built-in support for reading it.
% as /dev/null -o a.o
% rm -f b.a && ar rc b.a a.o
% ar t b.a
a.o
One may add other types of files to .a but that is almost assuredly a bad thing.
% rm -f a.a && ar rc a.a a.o b.a  # archive in archive, bad
% ar t a.a
a.o
b.a
% echo hello > a.txt
% rm -f a.a && ar rc a.a a.o a.txt  # text file in archive, bad
The original linker designers noticed that for many programs not every member was needed, so they tried to allow the linker to skip unused members. Therefore, they invented the interesting but confusing archive member extraction rule. See Symbol processing#Archive processing for details.
…Why isn't ld.lld faster?
Updated in 2022-11.
LLD is the LLVM linker. Its ELF port is typically installed as ld.lld. This article makes an in-depth analysis of ld.lld's performance.
The topic has been in my mind for a while.
Recently Rui Ueyama released mold 1.0 and people wonder why with multi-threading its ELF port is faster than ld.lld.
So I finally completed the article.
First of all, I am very glad that Rui Ueyama started mold. Our world has a plethora of compilers, but not many people learn or write linkers. As its design documentation says, there are many drastically different designs which haven't been explored. In my view, mold is innovative in that it introduced parallel symbol table initialization, symbol resolution, and relocation scan which to my knowledge hadn't been implemented before, and showed us amazing results. The innovation gives existing and future linkers incentive to optimize further.
….init, .ctors, and .init_array
Updated in 2023-03.
In C++, dynamic initializations for non-local variables happen before the first statement of the main function.
All (most?) implementations just ensure such dynamic initializations happen before main.
As an extension, GCC supports __attribute__((constructor)) which can make an arbitrary function run before main.
A constructor function can have an optional priority (__attribute__((constructor(N)))).
Relative relocations and RELR
Updated in 2024-02.
(In celebration of my 2800th llvm-project commit) Happy Halloween!
This article describes relative relocations and how the RELR format can greatly decrease file sizes.
An ELF linker performs the following steps to process an absolute relocation type whose width equals the word size (e.g. R_AARCH64_ABS64, R_X86_64_64).
if (undefined_weak || (!preemptible && (no_pie || is_shn_abs)))
  link-time constant
else if (SHF_WRITE || znotext) {
  if (preemptible)
    emit a symbolic relocation (e.g. R_X86_64_64)
  else
    emit a relative relocation (e.g. R_X86_64_RELATIVE)
} else if (!shared && (copy_relocation || canonical_plt_entry)) {
  ...
} else {
  error
}
Note: in FDPIC ABIs, there is no single base address.
Relative relocations can still be used, but the runtime operation is not simply *loc += base.
All about Procedure Linkage Table
Updated in 2024-01.
Branch target
Many architectures encode a branch/jump/call instruction with PC-relative addressing, i.e. the distance to the target is encoded in the instruction. In an executable or shared object (called a component in ELF), if the target is bound to the same component, the instruction has a fixed encoding at link time; otherwise the target is unknown at link time and there are two choices:
- text relocation
- indirection
In All about Global Offset Table, I mentioned that linker/loader developers often frowned upon text relocations because the text segment will be unshareable. In addition, the number of relocations would be dependent on the number of calls, which can be large.
…Build glibc with LLD 13
LLD is the LLVM linker.
It started at the end of 2011 as a work-in-progress rewrite of ld64 for the Mach-O binary format based on the atom model.
COFF and ELF ports based on the atom model were contributed subsequently.
They shared one symbol resolution model.
(IMO due to Mach-O's unfortunate limitation of 255 section .subsections_via_symbols was invented. The atom model was an incarnation of the concept but it did not fit into ELF/PE where sections are the better basic units.)
In 2015, both COFF and ELF ports were rewritten. (See "LLD improvement plan") Today, LLD is a mature and fast linker supporting multiple binary formats (ELF, Mach-O, PE/COFF, WebAssembly). FreeBSD, Android, and Chrome OS have adopted it as the main linker.
As a main contributor of LLD's ELF port who has fixed numerous corner cases in recent years, I consider that its x86-64 support has been mature since the 8.0.0 release and is in a great shape since 9.0.0. The AArch64 and PowerPC32/PowerPC64 support has been great since the 10.0.0 release. The 11.0.0 release has very solid linker script support. (When people complain that GNU ld's linker script is not immediately usable with LLD, it is almost assuredly the problem of the script itself.) So, what's next? Build glibc with LLD!
…All about Global Offset Table
Updated in 2025-05.
In ELF, the Global Offset Table is a memory region indexed by offsets, with entries holding constants and symbol addresses.
Symbol address
In an executable or shared object (called a component in ELF), a text section may need the absolute virtual address of a symbol (e.g. a function or a variable). The reference arises from an address taken operation or a PLT entry. The address may be:
- a link-time constant
- the load base plus a link-time constant
- dependent on runtime computation by ld.so
Extract an archive member to satisfy a DSO undef
In ELF linkers, undefined symbols from DSO participate in symbol resolution, just like undef from .o. The differences with undef from .o are:
- undef purely from DSO do not need .symtab entries
- --no-allow-shlib-undefined can error for such undef (-rpath-link ("load dependent libraries") behavior can suppress some errors.
ELF linkers extract an archive member to satisfy an undefined symbol from a shared object. Here is an example:
…COMDAT and section group
Updated in 2025-09.
The blog post explores how COMDAT (in the PE format) and section groups (in the ELF format) provide a mechanism to group related sections for efficient deduplication and garbage collection.
Vague linkage
In C++, inline functions, template instantiations, and a few other things can be defined in multiple object files but need deduplication at link time. In the dark ages the functionality was implemented by weak definitions: the linker does not report duplicate definition errors and resolves the references to the first definition. The downside is that unneeded copies remained in the linked image.
…SECTIONS and OVERWRITE_SECTIONS
The main task of a linker script is to define extra symbols and define how input sections map into output sections. It has other miscellaneous features which can be implemented via command line options:
- The
ENTRYcommand can be replaced by--entry. - The
OUTPUT_FORMATcommand can usually be replaced by-m. - The
SEARCH_DIRScommand can be replaced by-L. - The
VERSIONcommand can be replaced by--version-script. - The
INPUTandGROUPcommands can add other files as input. This provides a mechanism to split an archive/shared object into multiple files.
Symbol processing
UNDER CONSTRUCTION (COFF, Mach-O)
Symbol processing is a major step in a linker. In most binary formats, the linker maintains a global symbol table and performs symbols resolution for each input file (object file, shared object, archive, LLVM bitcode file). Some command line options can define/undefine symbols as well. The symbol resolution can affect archive processing and many subsequent steps (LTO, relocation processing, as-needed shared objects, etc).
…Dependency related linker options
This article describes the dependency related linker options -z defs, --no-allow-shlib-undefined, and --warn-backrefs.
Deploying them in a build system can improve build health.
-z defs
…
ELF interposition and -Bsymbolic
This article describes ELF interposition, the linker option -Bsymbolic, and its friends. In the end, it will discuss an ambitious plan which I dubbed "the Last Alliance of ELF and Men".
Motivated by a great post by Daniel Colascione ("Python is 1.3x faster when compiled in a way that re-examines shitty technical decisions from the 1990s.") and a recent rant from Linus Torvalds on shared objects' performance issues, I have summarized the current unfortunate ELF state and filed some GCC/binutils feature requests. I believe the performance of our shared object oriented world will be no slower than one with mostly statically linked executables.
(I wrote -fno-semantic-interposition first but then realized reorganization would improve readability, so moved some parts and added some stuff to this new article.)
…-fno-semantic-interposition
Updated in 2022-05.
This article is a continuation to ELF interposition and -Bsymbolic.
It focuses on the GCC/Clang option -fno-semantic-interposition and why it can (sometimes incredibly) optimize -fPIC programs.
Weak symbol
Updated in 2026-03.
C/C++
GCC and Clang support __attribute__((weak)) which marks a symbol weak. The same effect can be achieved with a preprocessor directive #pragma weak symbol.
Object file format
In ELF, there are three main symbol bindings. The ELF specification says:
STB_LOCAL: Local symbols are not visible outside the object file containing their definition. Local symbols of the same name may exist in multiple files without interfering with each other.STB_GLOBAL: Global symbols are visible to all object files being combined. One file's definition of a global symbol will satisfy another file's undefined reference to the same global symbol.STB_WEAK: Weak symbols resemble global symbols, but their definitions have lower precedence.
The dark side of RISC-V linker relaxation
Updated in 2025-07.
This article introduces RISC-V linker relaxation and describes the downside.
Linker optimization/relaxation
Because the linker has a global view and layout information, it can perform some peephole optimizations which are difficult/impossible to do on the compiler side. Generic link-time code sequence transformation is risky, because semantic information is lost and what the linker sees are byte streams. However, if every instruction in the candidate code sequence is associated with one ore more relocations, the ABI and the implementation can assign (additional) semantics to the relocation types and make such transformation safe. This technique is usually called linker optimization or linker relaxation. It seems that the term "linker optimization" is often used when the number of bytes does not change while "linker relaxation" is used when the number of bytes decreases.
…Linker garbage collection
A program may have a lot of unused code and data. There can be many reasons:
…Metadata sections, COMDAT and SHF_LINK_ORDER
Updated in 2025-09.
Modern compilers create metadata sections to support instrumentation, debugging, profiling, and other features.
These sections should be retained when their associated code is kept and discarded when their code is removed-but achieving this requires careful linker considerations.
This post explores the evolution of solutions, from early workarounds to modern mechanisms like section groups and SHF_LINK_ORDER, examining their trade-offs and real-world applications.
Metadata sections: properties and categories
Metadata sections usually have the following property:
- Relocations within a metadata section refer to its associated text section or any other auxiliary metadata sections. In many applications, a metadata section doesn't need additional auxiliary sections.
- Text sections don't have relocations that point to their metadata section. In some cases, a text section might reference its metadata section, but this means that the text section can't be inlined into another.
LLD and GNU linker incompatibilities
Updated in 2024-06.
Subtitle: Is ld.lld a drop-in replacement for GNU ld?
The motivation for this article was someone challenging the "drop-in replacement" claim on LLD's website (the discussion was about Linux-like ELF toolchain):
LLD is a linker from the LLVM project that is a drop-in replacement for system linkers and runs much faster than them. It also provides features that are useful for toolchain developers.
99.9% pieces of software work with ld.lld without a change. Some linker script applications may need an adaption (such adaption is oftentimes due to brittle assumptions: asking too much from GNU ld's behavior which should be fixed anyway). So I defended for this claim.
…All about symbol versioning
Updated in 2026-01.
Many people just want to know how to define or reference versioned symbols properly. You may jump to Recommended usage below.
In 1995, Solaris' link editor and ld.so introduced the symbol versioning mechanism. Ulrich Drepper and Eric Youngdale borrowed Solaris' symbol versioning in 1997 and designed the GNU style symbol versioning for glibc.
gnu-gabi specification: https://sourceware.org/gnu-gabi/program-loading-and-dynamic-linking.txt#:~:text=versioning
…Explain GNU style linker options
Updated in 2025-02
(首先庆祝一下LLVM 2000 commits达成!)
Compiler driver options
Before describing the linker options, let's introduce the concept of driver options.
The user-facing options of gcc and clang are called driver options.
Some driver options affect the options passed to the linker.
Many such options have the same name as the linker's, and they often have additional functions in addition to the options of the same name passed to the linker, such as: